Run Qwen3-Coder Locally (30B, 19 GB)
Qwen3-Coder 30B-A3B on Ollama: 19 GB Q4_K_M, Apache 2.0, 256K context, no data to Alibaba. Hardware guide for RTX 4090 and Apple Silicon.
Qwen3-Coder 30B-A3B is Alibaba's open-weight coding model that runs in 19 GB on a single RTX 4090 or a 24 GB Apple Silicon Mac via Ollama. Pull it with ollama pull qwen3-coder:30b, set it as the default model in Typilot Preferences, and every Polish and Notes command runs on your hardware - nothing reaches Alibaba or any other server.
Here is the hardware breakdown, how to set it up, and where it sits honestly compared to cloud coding assistants.
What Qwen3-Coder is
Qwen3-Coder is Alibaba's coding-specialist open-weight model family, released under the Apache 2.0 licence. The 30B-A3B variant is the consumer tier: 30 billion total parameters in a mixture-of-experts (MoE) architecture that activates approximately 3.3 billion parameters per forward pass. Because only 3.3B params compute on each token, inference is faster and lighter than a 30B dense model would be.
The context window is 256,000 tokens - roughly 192,000 words - which covers large codebases without truncation.
The 480B flagship exists on Ollama but requires approximately 290 GB of memory, making it server-class. It is not the model to pull for local use. The 30B-A3B is the consumer option; the "Next" generation (80B, ~52 GB) is also server-class for most home hardware.
Hardware requirements
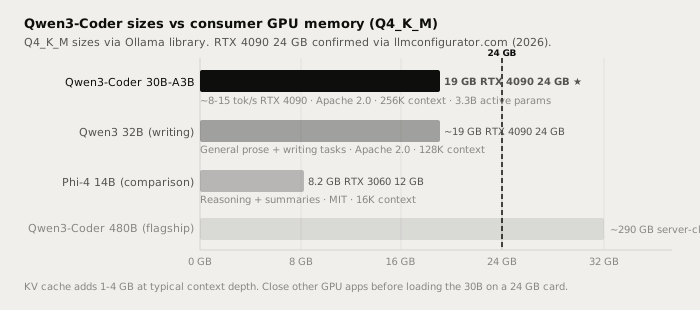
At Q4_K_M the 30B-A3B download is approximately 19 GB. Add KV-cache overhead (1-4 GB at typical coding context depths) and the working footprint sits at 21-23 GB.
| Hardware | VRAM / RAM | Result |
|---|---|---|
| RTX 5090 (32 GB) | 32 GB | Comfortable; full context available |
| RTX 4090 / RTX PRO 24G (24 GB) | 24 GB | Fits; close other GPU apps first |
| RTX 5060 Ti (16 GB) | 16 GB | Too small for the 19 GB download |
| M4 Max / M4 Ultra / M5 Pro (36 GB+) | 36 GB+ | Comfortable on Apple Silicon |
| M4 Pro / M5 (24 GB) | 24 GB | Fits at short context; 36 GB recommended for 256K |
| 64+ GB DDR5 system RAM (no GPU) | CPU only | 3-8 tok/s; usable for low-volume tasks |
RTX 4090 note: Windows display overhead consumes 1-2.5 GB, leaving 21-23 GB free. The model loads; close Discord overlays and other GPU workloads before inference.
Mac note: Metal acceleration applies automatically via Ollama's MLX runner on Apple Silicon (default since Ollama v0.40.0). No separate build is needed.
Running it in Ollama
The current Ollama stable release is v0.40.5 (October 14, 2026). Qwen3-Coder has been in the Ollama library since mid-2025 with 4.5 million downloads.
# Pull the 30B consumer build (~19 GB download)
ollama pull qwen3-coder:30b

# Run interactively
ollama run qwen3-coder:30b

# Quick smoke test
ollama run qwen3-coder:30b "Write a Python function that reads a CSV and returns a summary dict."

# Check your version first
ollama --version
After pulling, open Typilot Preferences, go to Models, and select Qwen3-Coder from the list of downloaded Ollama models. Set it as the default for Polish or Notes commands. The Ollama setup docs cover the full connection flow.
Quality and honest limits
| Task | Qwen3-Coder 30B local | Claude Sonnet / Fable (cloud) |
|---|---|---|
| Code completion, single function | Very good | Excellent |
| Code comment and docstring dictation | Very good | Excellent |
| Refactoring a known pattern | Very good | Excellent |
| Commit message from diff | Very good | Excellent |
| Novel multi-file architecture design | Good | Excellent |
| Long-form creative prose (non-code) | Adequate | Excellent |
| Audio and code leave device | Never | Always |
| Works offline | Yes | No |
| Per-request cost | $0 | Pay-per-token |
| Rate limits | None | Applies |
Qwen3-Coder 30B handles code completion, refactoring, docstrings, and commit message drafting reliably - the everyday coding tasks that make up most of a developer's dictation workload. The honest gap is on novel multi-file architecture decisions and long multi-step reasoning chains, where Claude Sonnet and Fable still produce more robust outputs. Local wins on everything that requires privacy, offline operation, high volume, or zero marginal cost.
Qwen3-Coder 30B-A3B is among the strongest open-weight coding models that fit a single consumer GPU. It runs at localhost:11434 - nothing reaches Alibaba during inference. For the privacy-sensitive coding assistant use case - medical, legal, or proprietary code - local is not the second-best option, it is the right one.
Qwen3-Coder vs general writing models
Qwen3-Coder is tuned for code and agent tasks. If most of your Typilot workload is prose writing - emails, meeting notes, document summaries - the general Qwen3 32B (~19 GB) or Phi-4 14B (8.2 GB) may produce better results for non-code text. For a direct model comparison across the main open-weight families, see Qwen vs Llama vs Gemma: local use.
If you want the strongest local model that fits 24 GB, Nemotron 3.5 Bolt (22 GB, 74B-A9B) gives broader general-purpose capability including vision input. Qwen3-Coder wins for pure coding tasks; Nemotron 3.5 Bolt wins if you need a single model for both code and general writing.
Privacy and the local-first guarantee
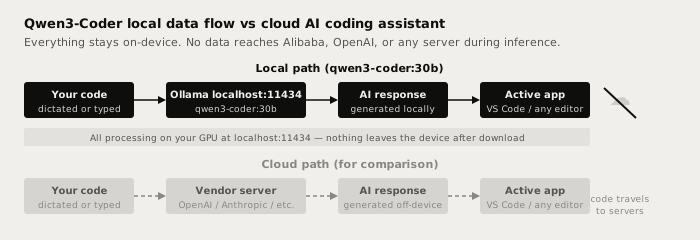
Every prompt you send through Ollama goes to localhost:11434 and is processed on your GPU. The network does not transmit during inference - verify this yourself: pull the model, disconnect your internet, and run a command in Typilot. Everything keeps working.
This matters for proprietary code. A SaaS coding assistant sends every prompt to vendor infrastructure, where it may be logged, processed, or used under the vendor's data policies. Local weights under Apache 2.0 have no such path. The code never leaves your machine.
For the full architecture explanation, see the Typilot security page. For the RAM and VRAM breakdown across all local model sizes, see how much RAM you need to run a local LLM.
The short version
Qwen3-Coder 30B-A3B is Alibaba's best open-weight coding model for a single consumer GPU: Apache 2.0, 19 GB at Q4_K_M, ollama pull qwen3-coder:30b. It activates 3.3B parameters per token over a 256K context window and handles code completion, refactoring, docstrings, and commit messages reliably. Cloud coding assistants still win on complex multi-file architecture; local wins on privacy, offline use, and zero per-token cost.
Pull the model, connect it to Typilot, and your code never leaves the device. Try it free for three days at /download. The architecture proof is at /security.
Common questions.
What is the minimum GPU for Qwen3-Coder 30B?+
An RTX 4090 24 GB or an M4 Pro Mac with 24 GB unified memory. At Q4_K_M the model file is ~19 GB; KV cache adds 1-4 GB, so you need at least 22-23 GB of available VRAM. Close other GPU-heavy apps before loading on a 24 GB card. A 32 GB card (RTX 5090) removes that constraint entirely.
Does running Qwen3-Coder locally send data to Alibaba?+
No. Ollama runs at localhost:11434 and processes everything on your hardware. After the one-time model download (~19 GB), no network traffic occurs during inference. The weights are Apache 2.0 and run entirely offline - nothing reaches Alibaba or any other server.
What is the Ollama pull command for Qwen3-Coder?+
`ollama pull qwen3-coder:30b` for the 30B consumer build at ~19 GB. The 480B flagship requires approximately 290 GB of memory and is server-class - not suitable for consumer hardware. Always specify the :30b tag for local use.
How does Qwen3-Coder 30B compare to Claude Sonnet for coding?+
Claude Sonnet and Fable give stronger multi-step reasoning and handle novel multi-file architecture decisions more robustly. Qwen3-Coder 30B handles everyday coding tasks - completions, refactors, docstrings, commit messages - reliably on consumer hardware. Local wins on privacy (nothing leaves the device), offline use, zero per-token cost, and no rate limits.