whisper.cpp vs faster-whisper for Dictation
whisper.cpp vs faster-whisper for local dictation: published CPU and GPU benchmarks, RAM use, int8 speed, and which runtime to pick.
The short answer: for dictation the two are close enough that ease of setup matters more than speed. In the faster-whisper maintainers' own benchmarks, whisper.cpp and faster-whisper finish within a few seconds of each other on a GPU, and faster-whisper with int8 quantisation is the quickest on a desktop CPU. Both are far faster than the original openai/whisper package, and both run entirely on your machine.
Here is what the published numbers say, what they do not measure, and how to choose.
What each one is
whisper.cpp is a C/C++ port of OpenAI's Whisper. It has no Python dependency and uses Metal on Apple Silicon, CUDA on NVIDIA GPUs and an optimised CPU path elsewhere.
faster-whisper reimplements Whisper on top of CTranslate2, a fast inference engine for Transformer models. It is a Python package, supports int8 quantisation on CPU and GPU, and adds batched transcription. The latest PyPI release at the time of writing is 1.2.1 (31 October 2025).
CPU: faster-whisper int8 is quickest
The faster-whisper README transcribes 13 minutes of audio with the small model on an Intel Core i7-12700K using 8 threads and beam size 5.
| Implementation | Precision | Time | RAM |
|---|---|---|---|
| openai/whisper | fp32 | 6m58s | 2335 MB |
| whisper.cpp | fp32 | 2m05s | 1049 MB |
| faster-whisper | fp32 | 2m37s | 2257 MB |
| faster-whisper | int8 | 1m42s | 1477 MB |
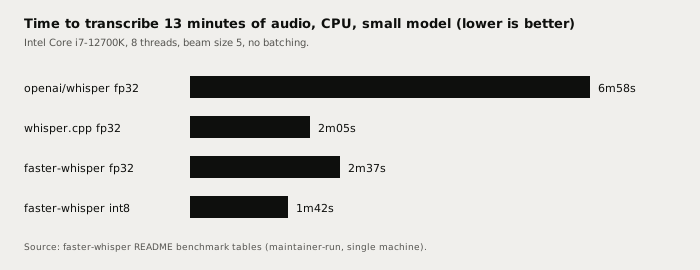
Two things stand out. whisper.cpp beats faster-whisper at the same fp32 precision and uses about half the RAM, while faster-whisper wins once you let it quantise to int8. Dividing the 13 minutes (780 seconds) by each time gives a rough speed multiple: about 6.2x real time for whisper.cpp, 5.0x for faster-whisper fp32 and 7.6x for faster-whisper int8. Anything above 1x keeps up with speech.
GPU: effectively a tie
The same README tests the large-v2 model on an NVIDIA RTX 3070 Ti (8 GB) with CUDA 12.4, again on 13 minutes of audio.
| Implementation | Precision | Time | VRAM |
|---|---|---|---|
| openai/whisper | fp16 | 2m23s | 4708 MB |
| whisper.cpp (Flash Attention) | fp16 | 1m05s | 4127 MB |
| faster-whisper | fp16 | 1m03s | 4525 MB |
| faster-whisper | int8 | 59s | 2926 MB |
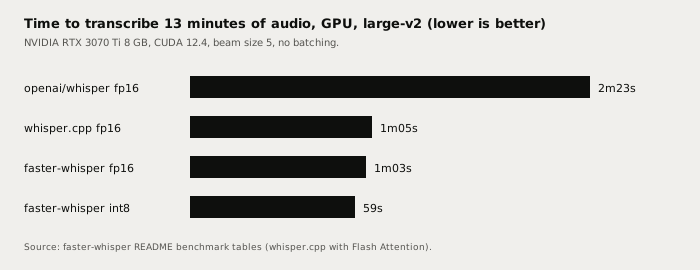
Two seconds separates whisper.cpp from faster-whisper at fp16, which is noise for any human workflow. faster-whisper's int8 mode trades a little precision for about 35% less VRAM than its fp16 run (2926 MB against 4525 MB).
These tables are published by the faster-whisper maintainers, on one CPU and one GPU, and they measure throughput on a long file. They do not measure the thing dictation depends on: how quickly a 5-second clip comes back after you stop talking. Treat them as a ranking, then time a short clip on your own machine.
What the benchmarks leave out
Batching is where faster-whisper pulls well ahead. With batch_size=8 it transcribed the 13-minute file in 17 seconds on the GPU. That is excellent for processing a recorded meeting, but dictation produces one short clip at a time, so there is nothing to batch.
Accuracy is also not the variable. Both run the same Whisper weights, so the model you choose matters far more than the runtime. See which Whisper model size to pick for dictation for the memory and error-rate trade-offs.
Which should you use?
| Your situation | Pick |
|---|---|
| Apple Silicon Mac, want a single binary | whisper.cpp |
| No Python, minimal dependencies | whisper.cpp |
| Python project, CPU only, want fastest | faster-whisper with int8 |
| Transcribing long recordings in bulk | faster-whisper with batching |
| Tight on RAM | whisper.cpp fp32 (1049 MB) or faster-whisper int8 |
Neither is a dictation app. Both transcribe a file or a stream, and you still have to build the microphone capture, hotkey, voice-activity detection and text insertion around them. The walkthrough in run Whisper locally for dictation shows the DIY route, and fixing Whisper hallucinations on silence covers the quirk you will hit once it is running.
Skip the assembly
If you want local dictation without choosing a runtime, Typilot packages on-device Whisper with a system-wide hotkey so you can dictate into any app. Audio is transcribed on your device and never uploaded, which you can read about on the security page. For the wider engine comparison, see Whisper large-v3-turbo vs Parakeet.
The short version
On the published benchmarks whisper.cpp and faster-whisper are a near tie on GPU, and faster-whisper int8 is the fastest on a desktop CPU, while whisper.cpp uses the least RAM at fp32. Both run Whisper locally with no cloud, and both are several times faster than the original package. Pick whisper.cpp for simplicity and Apple Silicon, faster-whisper for Python and batch work, and choose the model size before you worry about the runtime. To skip the setup, download Typilot and try it free for 3 days, and read the security page for how audio stays on your device.
Common questions.
Is faster-whisper faster than whisper.cpp?+
It depends on hardware and precision. In the faster-whisper README (13 minutes of audio), the two are within 2 seconds on an RTX 3070 Ti with large-v2 (1m05s vs 1m03s). On an Intel i7-12700K with the small model, whisper.cpp fp32 took 2m05s, faster-whisper fp32 took 2m37s and faster-whisper int8 took 1m42s.
Which uses less memory, whisper.cpp or faster-whisper?+
At fp32 on CPU with the small model, whisper.cpp used about 1049 MB of RAM against 2257 MB for faster-whisper. With int8 quantisation faster-whisper drops to about 1477 MB. On GPU with large-v2, whisper.cpp used 4127 MB of VRAM and faster-whisper int8 used 2926 MB.
Do whisper.cpp and faster-whisper give different accuracy?+
Both run the same OpenAI Whisper model weights, so accuracy is driven mainly by the model size you choose (tiny to large) rather than the runtime. Quantisation can shift results slightly, so check your own audio if you switch to int8.
Which one should I use for local dictation?+
Use whisper.cpp if you want a single binary with no Python, especially on Apple Silicon. Use faster-whisper if you work in Python, want the fastest CPU speed with int8, or batch-process long recordings. For live dictation the speed gap is small, so pick on setup effort and then time a short clip on your own machine.